Key Takeaways:
- A network blind spot is an infrastructure device, dependency, path, or traffic pattern that is missing from operational visibility.
- Common causes include stale diagrams, incomplete inventories, hybrid environments, limited monitoring coverage, and unclear ownership.
- Live maps and auto-discovery help teams maintain a more accurate view as infrastructure changes.
- Monitoring availability alone is not enough—response time, packet loss, utilization, service health, and other signals may reveal early warning signs.
- Traffic analysis helps explain bandwidth changes that an up-or-down status cannot explain.
- Effective alerting connects each condition to the right owner, threshold, timing, and escalation path.
Remember when you learned how to drive? Undoubtedly whoever taught you the rules of the road explained the danger of “blind spots”—those triangular areas on either side of the car in which your peripheral vision fails you. Unless you look over your shoulder while changing lanes, you could all-too-easily hit an unsuspecting occupant of the blind spot zone.
Network blind spots can be just as dangerous in an IT environment that a team cannot reliably see, monitor, or explain. A blind spot might be an unknown device, an undocumented connection, a virtual workload, a cloud-connected dependency, or network traffic that is not being analyzed. These gaps make it harder to detect change, locate the source of a problem, and respond before users are affected.
The most effective way to reduce network blind spots is to combine automatic device discovery, live network mapping, continuous monitoring, meaningful alerts, and traffic or performance analysis. Together, these capabilities give IT teams a clearer operational view of what is happening now, why it is happening, and what may need to change next.
What is a Network Blind Spot?
A network blind spot is a part of the network or supporting IT environment that is not included in current documentation, monitoring, or analysis. It can be a device that was never added to an inventory, a link that is missing from a diagram, a server that is monitored only for availability, or a cloud-connected service path that no one is watching from end to end.
Blind spots do not always mean a team is doing something wrong. Networks change constantly. New devices connect, workloads move, sites are added, remote users depend on different paths, and services become dependent on systems that may sit outside the traditional network boundary. The risk comes when the operational view does not change with the environment.
What Causes Network Blind Spots?
1. Stale diagrams and incomplete inventories
A static network diagram can become inaccurate as soon as a device moves, a link changes, or a new system is connected. Manual inventories are also easy to leave behind during a project or infrastructure change. When teams cannot confirm what is connected or where it belongs, troubleshooting takes longer and ownership becomes unclear.
2. Unknown or unapproved devices
Devices can appear outside a formal change process, especially in distributed offices, lab environments, temporary projects, or organizations with multiple IT teams. The issue is not only whether the device is approved. It is whether the team knows it exists, understands what it supports, and can see its current status.
3. Hybrid, virtual, and remote environments
Traditional monitoring plans often focus on core routers, switches, and on-premises servers. That approach can miss virtual systems, cloud-connected workloads, branch connections, VPNs, internet edges, and local dependencies that affect a service path. A cloud application may be available while a local gateway, firewall, link, or identity service prevents users from reaching it.
4. Monitoring only whether something is up or down
Availability is important, but it is only one part of infrastructure health. A device can be reachable while response time increases, packet loss appears, utilization approaches a limit, or an application service begins to degrade. If monitoring does not include the signals that matter for each system, a team may not see a problem until users report it.
5. Missing traffic context
Utilization tells you how busy a link is, but not necessarily what is creating the demand. Without traffic analysis, it can be difficult to identify top talkers, applications, conversations, or unusual communication patterns. That makes bandwidth issues harder to explain and can lead to changes based on assumptions instead of evidence.
6. Siloed ownership and noisy alerts
A blind spot can also be operational. If network, systems, cloud, security, and service teams use separate views or do not share context, important signals may not reach the person who can act. Excessive alerts create a similar problem: when every condition generates the same urgency, meaningful changes are easier to miss.
How to Prevent Network Blind Spots
1. Discover and maintain a live network map
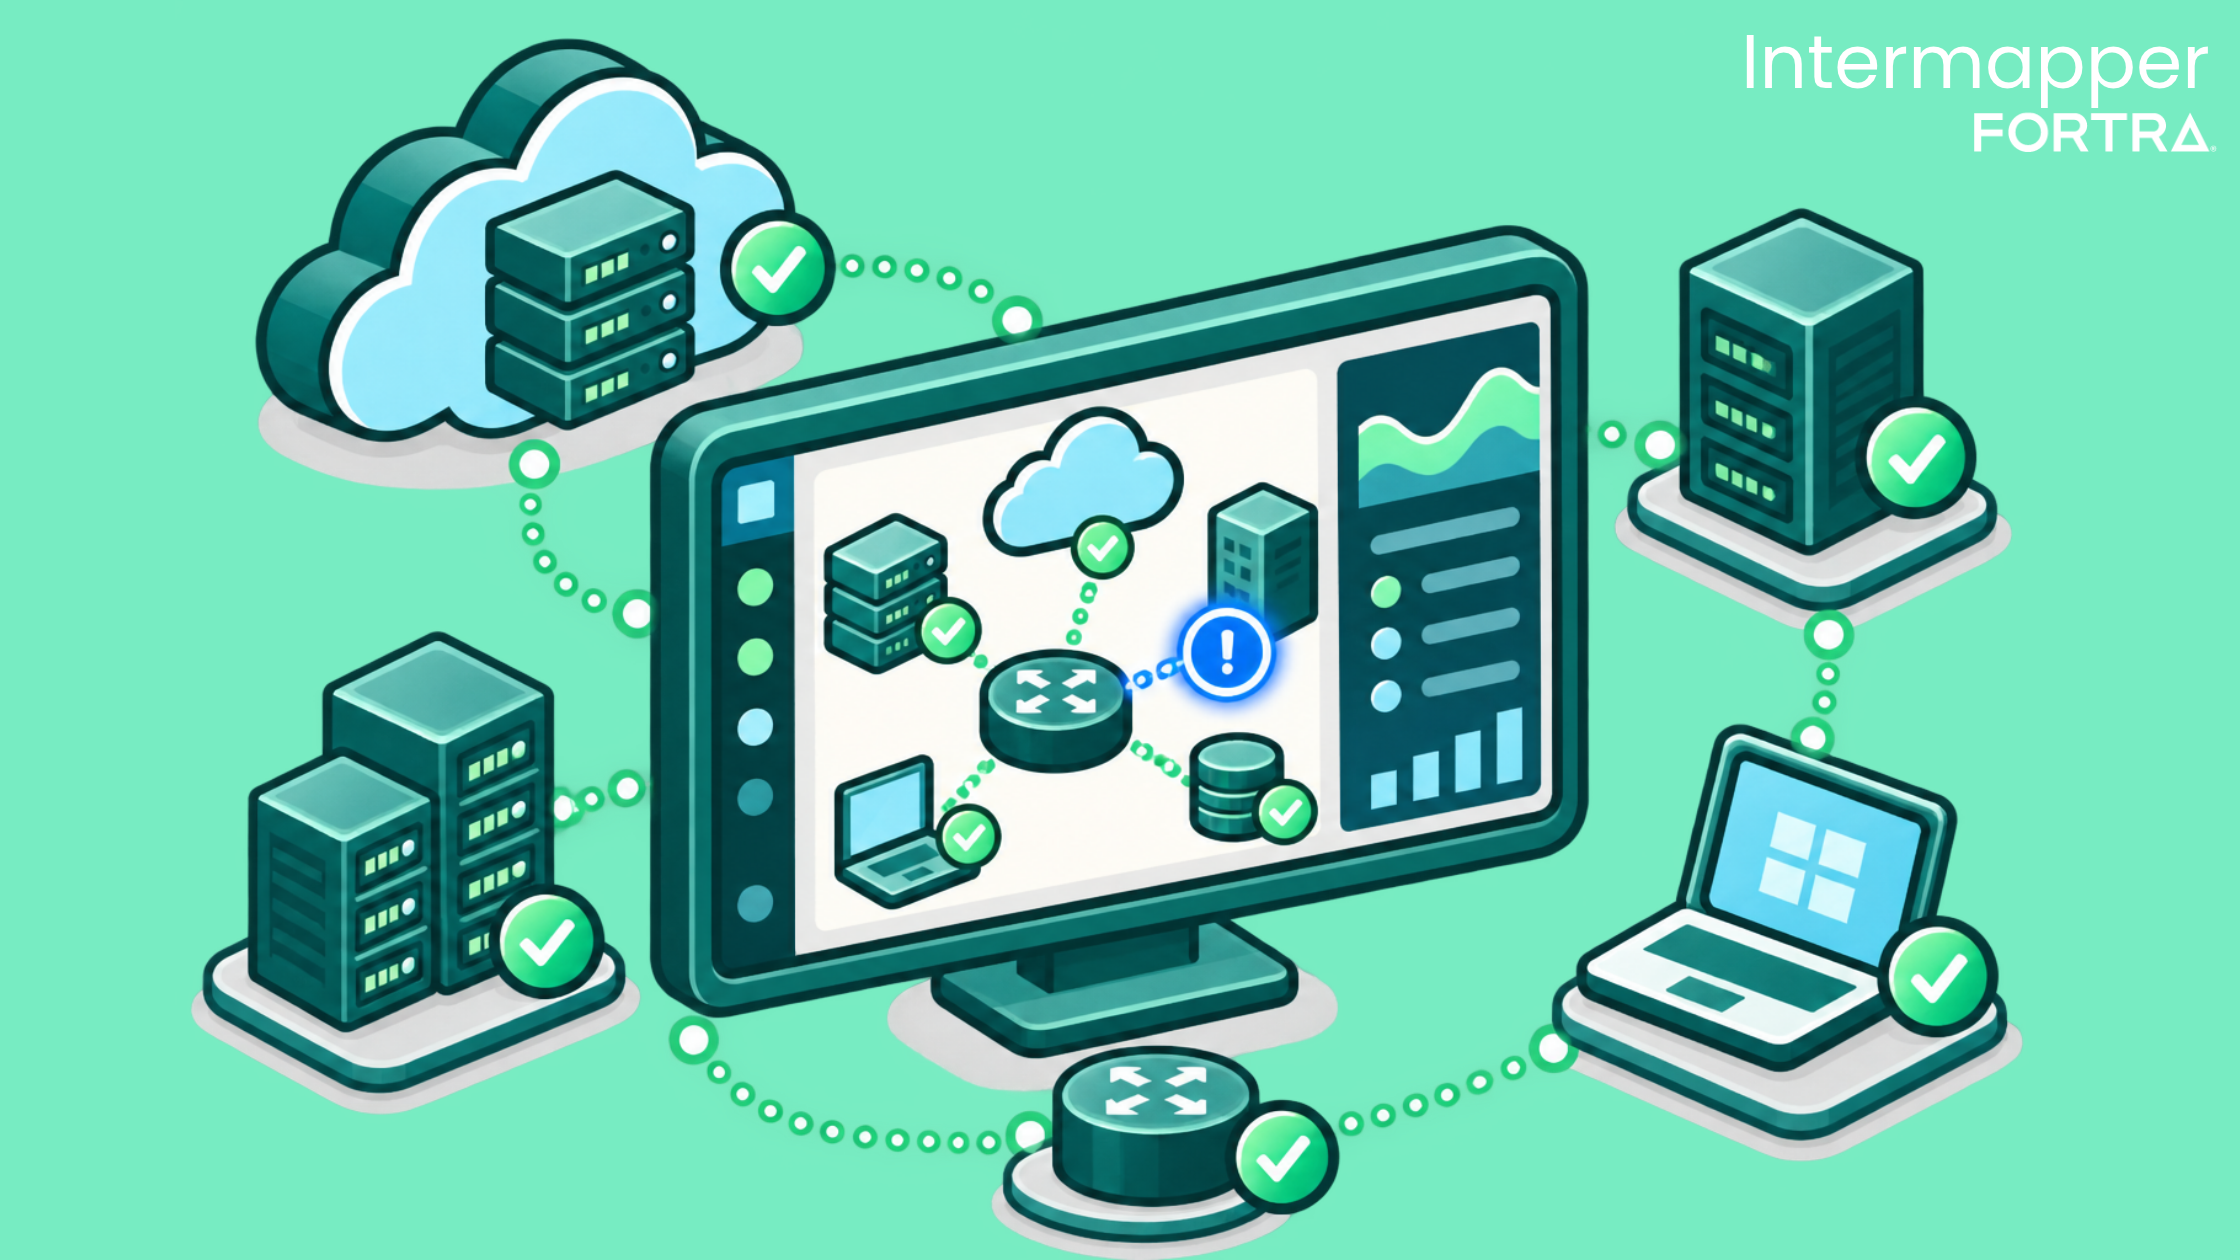
Use auto-discovery to identify IP-enabled devices across relevant subnets, sites, and distributed network scopes to map network devices. A live map should show more than device names. It should help the team understand status, relationships, and location so an operator can orient quickly during an incident. Live network maps are more useful than relying on a diagram that has to be updated separately every time the environment changes.
2. Define monitoring coverage around the service path
Start with the services users and business operations depend on, then work backward through the path that supports them. Include the devices, links, servers, applications, cloud-connected systems, and local dependencies that can affect availability or performance. This approach reduces the chance that monitoring covers individual components while missing the connection between them.
3. Monitor more than availability
Choose metrics that match the role of each system. Depending on the device or service, useful signals may include response time, packet loss, interface utilization, CPU or memory use, environmental conditions, application status, and other supported performance indicators. Establishing a baseline makes it easier to distinguish an ordinary fluctuation from a meaningful change.
4. Extend coverage with built-in and custom probes
Every environment has systems that do not fit a simple standard template. Built-in and custom network probes can extend monitoring to specialized devices, services, and application endpoints when the system exposes a practical health signal. The goal is not to collect every possible metric. It is to monitor the signals that help the team detect, locate, or explain issues.
5. Analyze traffic when utilization is not enough
When a link is busy or performance changes, inspect the traffic behind the metric to troubleshoot bandwidth issues. NetFlow, sFlow, jFlow, and cFlow data can help show who is communicating, what applications are active, which endpoints are using the most bandwidth, and how traffic patterns change over time. That context helps teams troubleshoot congestion and make better bandwidth decisions.
6. Connect alerts to ownership and escalation
An alert is most useful when it tells the right person what changed and what needs attention. Set thresholds that reflect meaningful conditions, use delays or repeat intervals to reduce noise, and define escalation rules for issues that remain unresolved. Review alert history regularly so the configuration continues to reflect how the environment actually operates.
7. Review visibility after every meaningful change
Network visibility is not a one-time project. Recheck maps, inventories, monitoring coverage, and alert ownership after migrations, acquisitions, new sites, major application changes, and other infrastructure updates. Historical performance and traffic trends can also reveal recurring blind spots that are not obvious during a single incident.
Network Blind Spot Prevention Checklist
Use these questions during a monitoring review or after a significant infrastructure change:
- Have all relevant subnets, sites, cloud-connected systems, virtual environments, and remote connections been discovered?
- Does the current map show device status and important relationships, or is it only a static reference diagram?
- Are critical servers, applications, links, and service dependencies monitored with the right signals?
- Can the team identify whether a performance issue is local, path-related, traffic-related, or inside a server or application?
- Can traffic analysis show what is consuming bandwidth when utilization increases?
- Does every important alert have an owner, a meaningful threshold, and an escalation path?
- When was the monitoring coverage last reviewed against the current environment?
How Intermapper Helps Reduce Network Blind Spots
Intermapper helps IT teams reduce network blind spots by connecting discovery, live maps, monitoring, alerting, and analysis in one operational view. The platform supports the three questions teams need to answer during everyday operations and incidents:
- See What's Happening: Intermapper Network & Server Monitoring automatically discovers and maps infrastructure, monitors devices and servers, and provides real-time status and notifications. Live maps help teams see relationships and locate trouble faster.
- Understand Why: Status, performance, and historical data add context to alerts. Intermapper Flows Insight provides deeper visibility into bandwidth and network traffic, while Intermapper Server Insight helps teams investigate performance inside supported server environments.
- Plan What's Next: Historical trends, reporting, and capacity-planning insights help teams turn operational data into better decisions about infrastructure changes and future demand with Intermapper Foresight.
Get a Clearer View of Your Network
Network blind spots are easier to prevent when your team can see what is connected, understand how systems are performing, and investigate changes with the right context. Intermapper helps bring live maps, monitoring, alerts, and traffic insight together so IT teams can detect issues earlier and troubleshoot with more confidence.
Reduce Network Blind Spots with Intermapper
See how Intermapper can help your team connect infrastructure monitoring, trend visibility, and forward-looking capacity planning.